Model governance and AI-assisted risk work
Keep model use bounded, reviewable, and accountable.
A model can be wrong in a sophisticated way. An AI assistant can write a fluent case note with an invented fact. Governance makes those failures visible before the output becomes an unchecked decision.
Use the current model-risk framework
The federal banking agencies issued revised model-risk guidance in April 2026 through SR 26-2, replacing SR 11-7 and SR 21-8. The letter states its expected relevance to Federal Reserve-regulated banking organizations over $30 billion in assets and emphasizes a risk-based approach. Applicability must be assessed for the actual institution.
For this textbook’s engineering design, maintain an inventory of models and their uses, owners, limitations, dependencies, and review evidence. A small rule-based model can still be important if it controls a large exposure. Governance effort should reflect the consequence and complexity of use rather than the prestige of the algorithm.
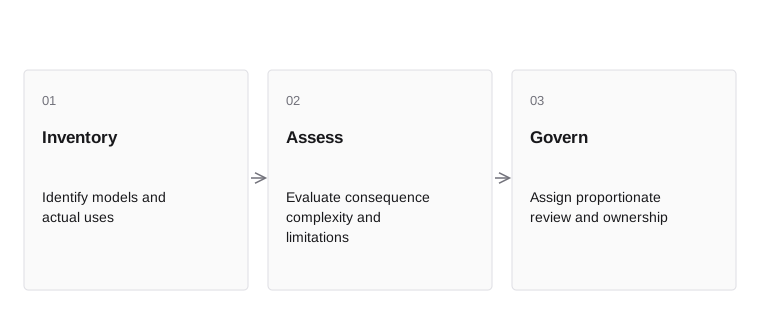
- InventoryIdentify models and actual uses
- AssessEvaluate consequence complexity and limitations
- GovernAssign proportionate review and ownership
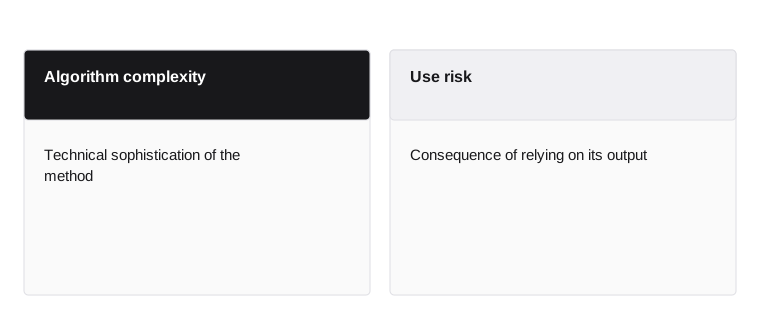
- Algorithm complexity
- Technical sophistication of the method
- Use risk
- Consequence of relying on its output
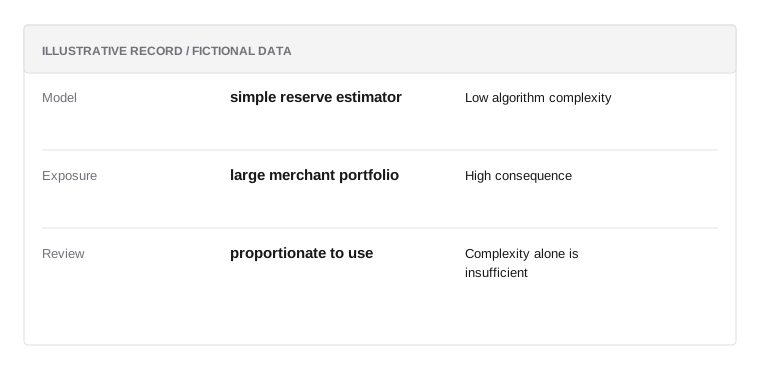
Model inventory
Illustrative data; not a real customer record or a prescribed policy.
- Modelsimple reserve estimator
Low algorithm complexity
- Exposurelarge merchant portfolio
High consequence
- Reviewproportionate to use
Complexity alone is insufficient
A simple model can support a consequential decision
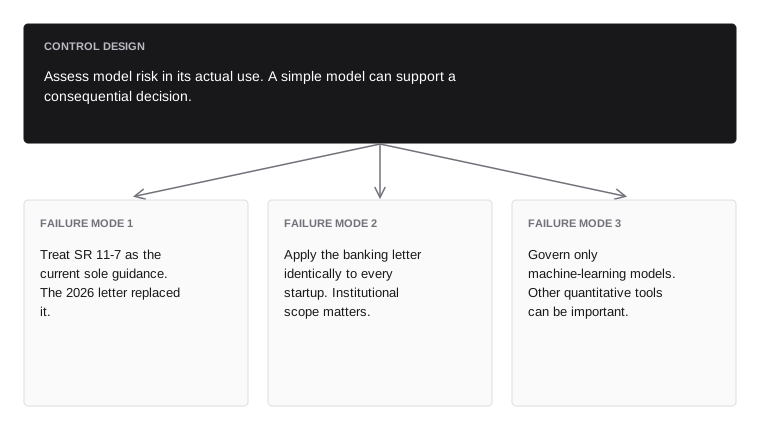
Assess model risk in its actual use. A simple model can support a consequential decision.
- Failure mode 1avoid
- Treat SR 11-7 as the current sole guidance. The 2026 letter replaced it.
- Failure mode 2avoid
- Apply the banking letter identically to every startup. Institutional scope matters.
- Failure mode 3avoid
- Govern only machine-learning models. Other quantitative tools can be important.
Separate development from effective challenge
Developers understand the model deeply, but they also know the assumptions they intended. Independent challenge tests whether those assumptions hold and whether the use is appropriate. The structure should fit the organization and applicable expectations.
Review conceptual soundness, data, implementation, outcomes, limitations, and controls. Track findings through remediation and retest. A reviewer’s signature is not evidence that every concern was resolved. The model owner should know which limitations remain and what use is permitted while they remain.
Effective challenge examines whether the model is suitable for its stated use, including limitations that the development team may not have emphasized. It can inspect the target, data, assumptions, validation evidence, implementation, and downstream policy. Independence is useful because the people responsible for delivery may face pressure to interpret ambiguous results favorably. The form and depth of review should fit the model’s materiality and the applicable framework.
A limitation becomes operational when it changes the permitted use. If a model has weak evidence for a new product segment, the response may be restricted deployment, more review, additional validation, or another approved control. Recording the limitation in a document while using the model without restriction does not manage it.
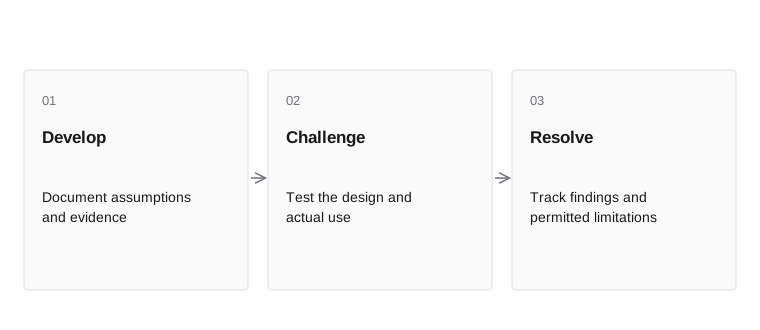
- DevelopDocument assumptions and evidence
- ChallengeTest the design and actual use
- ResolveTrack findings and permitted limitations
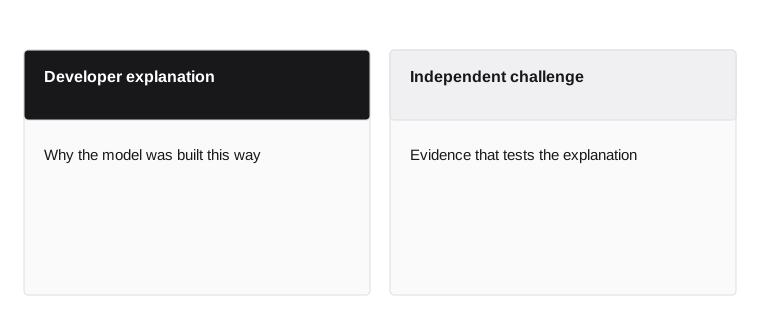
- Developer explanation
- Why the model was built this way
- Independent challenge
- Evidence that tests the explanation
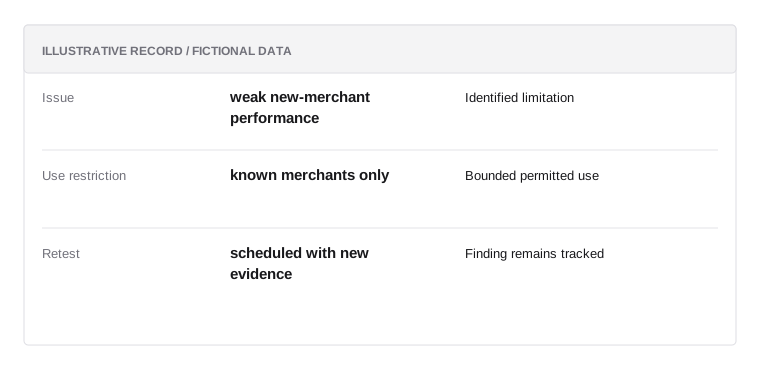
Review finding
Illustrative data; not a real customer record or a prescribed policy.
- Issueweak new-merchant performance
Identified limitation
- Use restrictionknown merchants only
Bounded permitted use
- Retestscheduled with new evidence
Finding remains tracked
Approval alone does not remove limitations
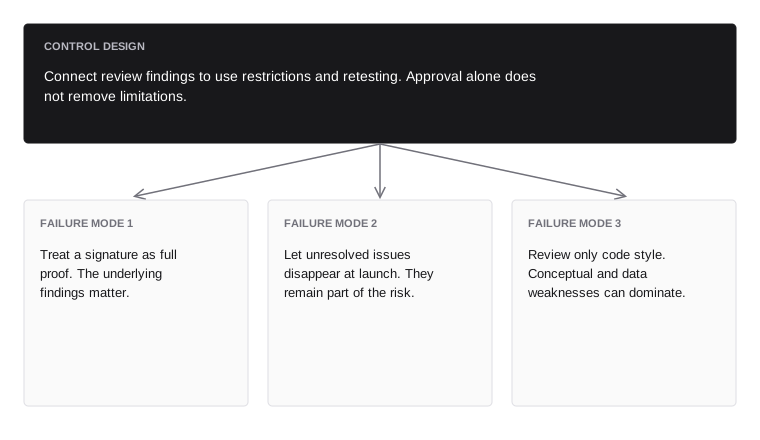
Connect review findings to use restrictions and retesting. Approval alone does not remove limitations.
- Failure mode 1avoid
- Treat a signature as full proof. The underlying findings matter.
- Failure mode 2avoid
- Let unresolved issues disappear at launch. They remain part of the risk.
- Failure mode 3avoid
- Review only code style. Conceptual and data weaknesses can dominate.
Bound generative AI to evidence-supported tasks
Generative AI can help summarize records, draft narratives, or retrieve relevant policy passages. It can also invent facts, omit context, or follow instructions embedded in untrusted documents. Treat retrieved customer material as evidence to analyze, not instructions to the system.
Use constrained inputs, source references, and a reviewable output. Require factual claims to point to supporting records. Keep sensitive reporting information within approved access boundaries. A model-generated narrative should not automatically file a report, release funds, or change a customer restriction without the authorized decision process.
A generative system can help summarize retained evidence, but fluent wording is not evidence. Each material factual statement should be traceable to the permitted source material, and the workflow needs a response when support is absent or contradictory. Treat retrieved documents and customer submissions as data rather than trusted instructions. Separate the assistant’s proposal from the authorized decision, especially when the action changes funds, account access, or a regulated process. Evaluation should include fabricated facts, missing evidence, private-data exposure, and misleading instructions embedded in source material.
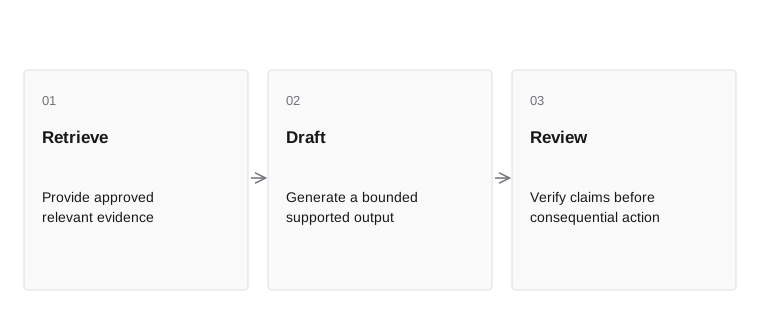
- RetrieveProvide approved relevant evidence
- DraftGenerate a bounded supported output
- ReviewVerify claims before consequential action
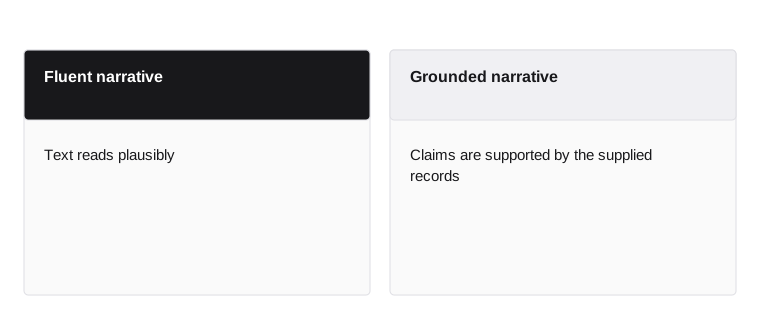
- Fluent narrative
- Text reads plausibly
- Grounded narrative
- Claims are supported by the supplied records
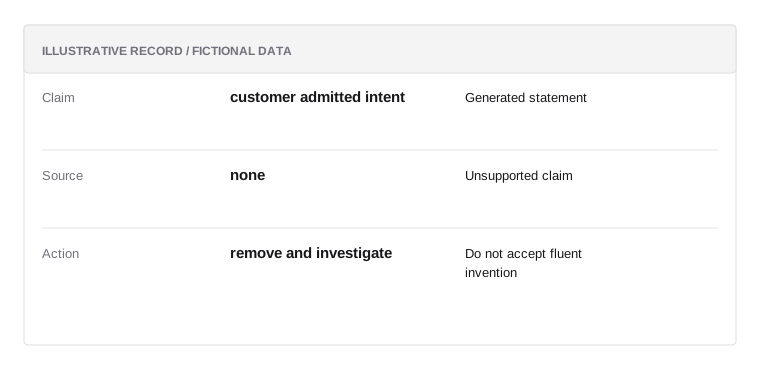
AI drafting record
Illustrative data; not a real customer record or a prescribed policy.
- Claimcustomer admitted intent
Generated statement
- Sourcenone
Unsupported claim
- Actionremove and investigate
Do not accept fluent invention
Fluency does not establish truth
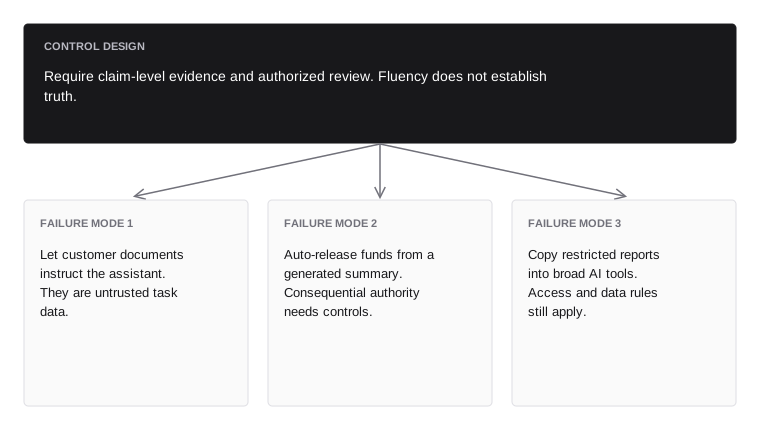
Require claim-level evidence and authorized review. Fluency does not establish truth.
- Failure mode 1avoid
- Let customer documents instruct the assistant. They are untrusted task data.
- Failure mode 2avoid
- Auto-release funds from a generated summary. Consequential authority needs controls.
- Failure mode 3avoid
- Copy restricted reports into broad AI tools. Access and data rules still apply.
Evaluate AI failure modes before use
An AI evaluation should reflect the actual task: factual accuracy, omissions, unsupported claims, confidentiality, instruction handling, and consistency. Include difficult cases and deliberate misleading content in controlled fixtures.
Measure the harm of errors, not only an average quality score. A rare invented admission can be more consequential than several awkward sentences. Compare against a useful baseline and define when a human must intervene. Version prompts, retrieval rules, models, and evaluation sets so a vendor update does not silently invalidate the evidence.
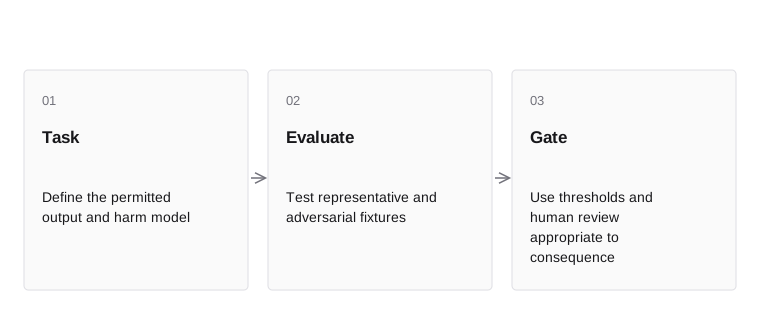
- TaskDefine the permitted output and harm model
- EvaluateTest representative and adversarial fixtures
- GateUse thresholds and human review appropriate to consequence
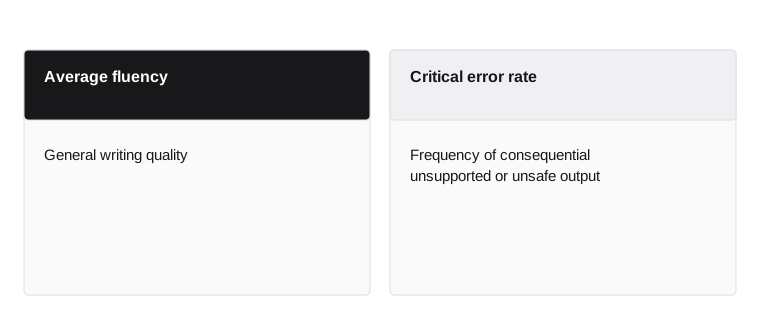
- Average fluency
- General writing quality
- Critical error rate
- Frequency of consequential unsupported or unsafe output
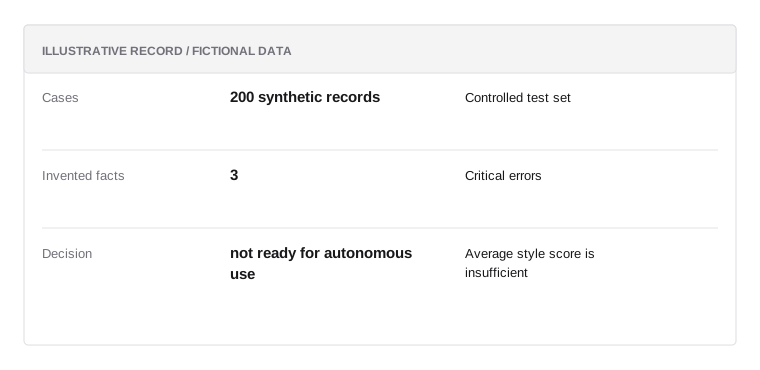
AI evaluation
Illustrative data; not a real customer record or a prescribed policy.
- Cases200 synthetic records
Controlled test set
- Invented facts3
Critical errors
- Decisionnot ready for autonomous use
Average style score is insufficient
A good average can hide unacceptable rare failures
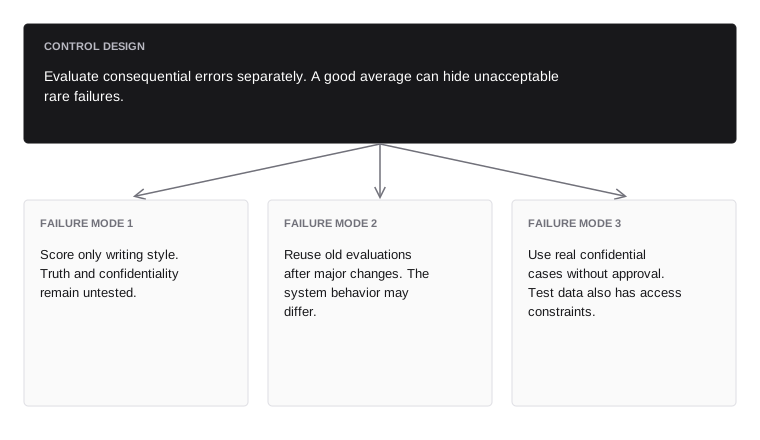
Evaluate consequential errors separately. A good average can hide unacceptable rare failures.
- Failure mode 1avoid
- Score only writing style. Truth and confidentiality remain untested.
- Failure mode 2avoid
- Reuse old evaluations after major changes. The system behavior may differ.
- Failure mode 3avoid
- Use real confidential cases without approval. Test data also has access constraints.
Maintain a complete change record
Model behavior can change through data, features, code, thresholds, prompts, retrieval sources, or vendor versions. Keep a release record that connects the change to evaluation, approval, rollout, monitoring, and rollback.
Define what counts as a material change and who decides. A prompt edit that adds a new tool can be more consequential than a model patch. Preserve the affected population and outputs for review under the retention policy. Governance is complete when the organization can explain what changed, why it was allowed, and how the result was checked.
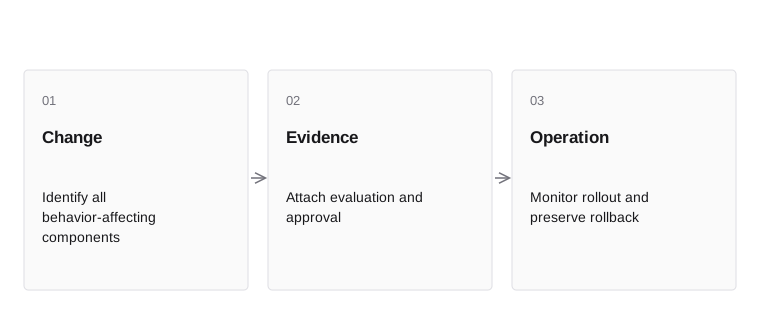
- ChangeIdentify all behavior-affecting components
- EvidenceAttach evaluation and approval
- OperationMonitor rollout and preserve rollback
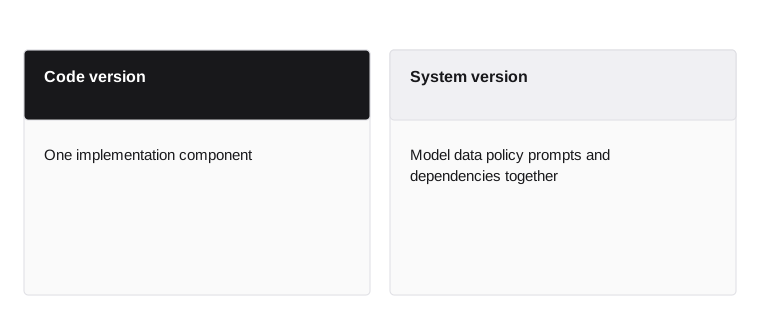
- Code version
- One implementation component
- System version
- Model data policy prompts and dependencies together
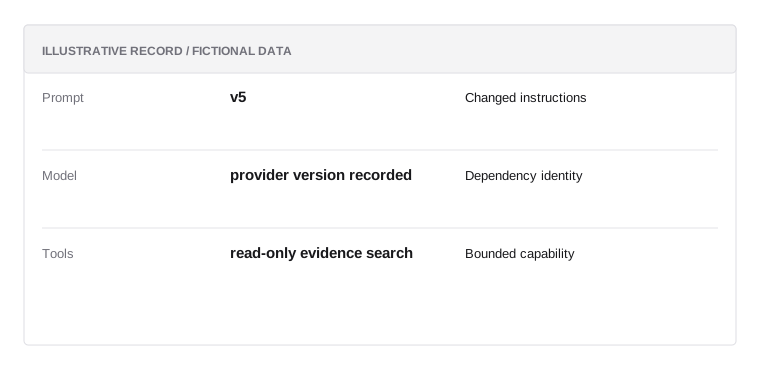
AI release record
Illustrative data; not a real customer record or a prescribed policy.
- Promptv5
Changed instructions
- Modelprovider version recorded
Dependency identity
- Toolsread-only evidence search
Bounded capability
Behavior can change outside application code
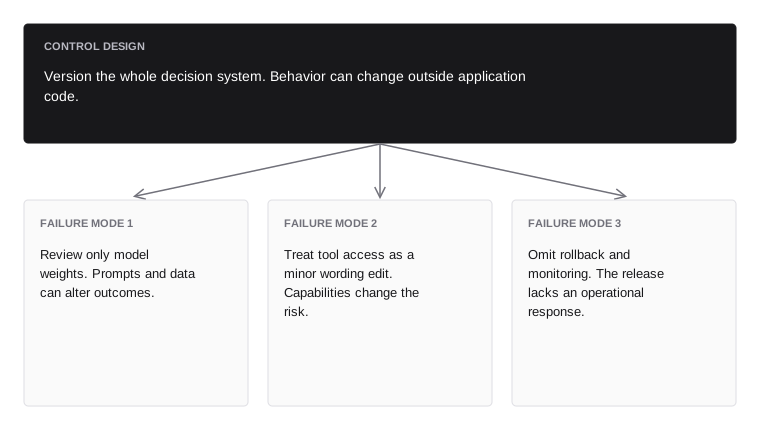
Version the whole decision system. Behavior can change outside application code.
- Failure mode 1avoid
- Review only model weights. Prompts and data can alter outcomes.
- Failure mode 2avoid
- Treat tool access as a minor wording edit. Capabilities change the risk.
- Failure mode 3avoid
- Omit rollback and monitoring. The release lacks an operational response.
Chapter connections
This chapter builds on Experiments, causal effects, and risk tradeoffs. Use the glossary for terminology and risk mathematics for formulas and worked calculations.